Comparison of Local LLMs
English | Japanese
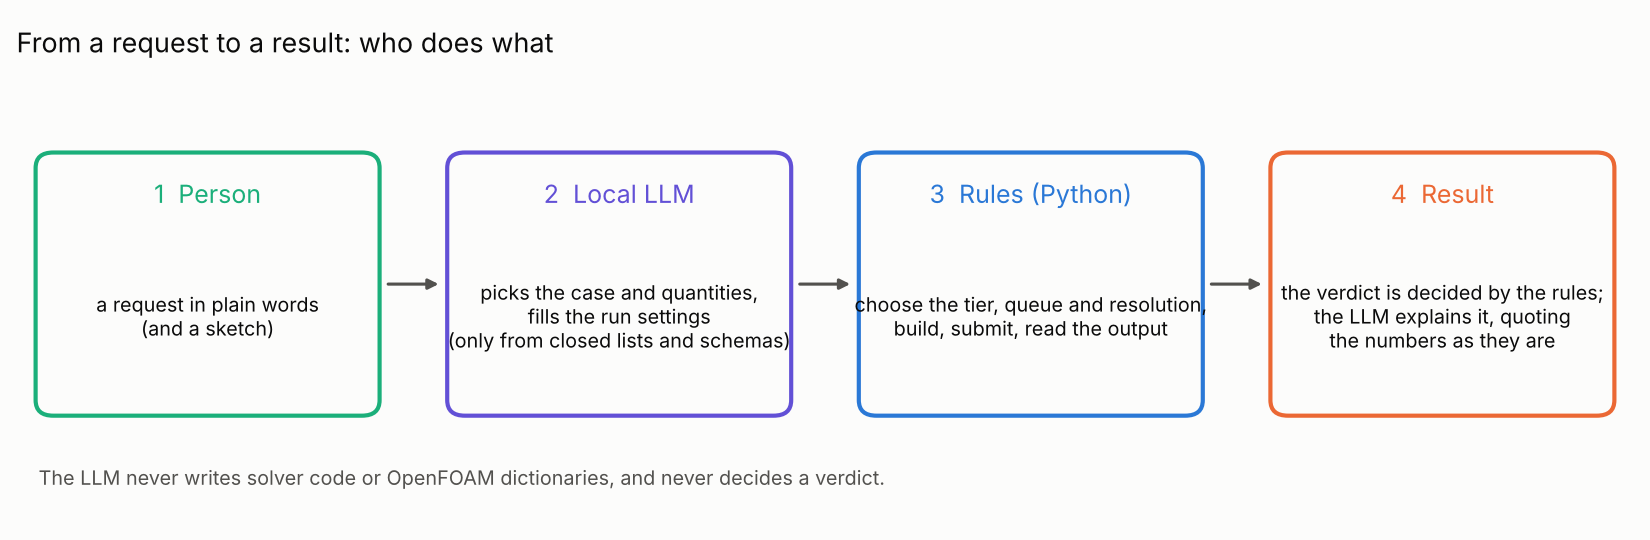
OpenRheo assumes two tiers: a high-performance cloud LLM as teacher, a local LLM on site as executor. This page compares local LLMs as measured on a GH200. How the agent asks the LLM and checks its answers is on The local-LLM agent.
Where the local LLM runs
One GH200 node has 120,857 MB of memory on the Grace CPU and 97,280 MB on the Hopper GPU (measured 2026-07-27). The local LLM is served by ollama on the GPU; every measurement below was taken that way. The model files take 4.7 GB (qwen2.5 7b) and 9.0 GB (qwen2.5 14b), and a 14b and a 72b model (about 9 + 45 GB) stay resident together on the 96 GB GPU. Running the LLM on the same GPU as an LBM run at the same time has not been measured.
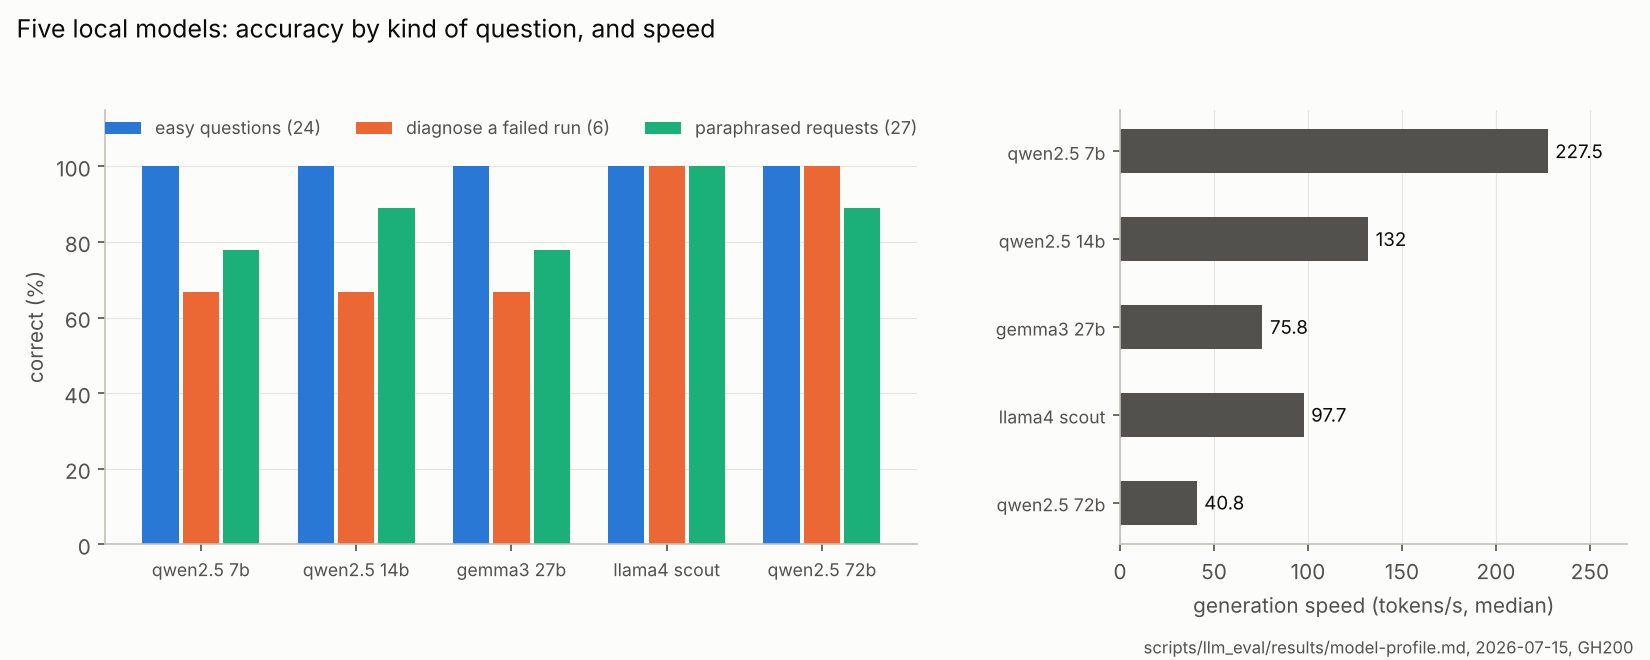
Measurements (2026-07-15, ollama on a GH200, Q4 quantisation)
| model | easy questions (24) | diagnose a failed run (6) | paraphrased requests (27) | generation, median tok/s | latency, median s |
|---|---|---|---|---|---|
| qwen2.5 7b | 24 | 4 | 21 | 227.5 | 0.3 |
| qwen2.5 14b | 24 | 4 | 24 | 132.0 | 0.6 |
| gemma3 27b | 24 | 4 | 21 | 75.8 | 1.2 |
| llama4 scout | 24 | 6 | 27 | 97.7 | 1.2 |
| qwen2.5 72b | 24 | 6 | 24 | 40.8 | 1.7 |
Every model answers the easy calls. The models differ only when they must diagnose a failed run from its log, and on paraphrased requests. So the calls are routed per call site (2026-08-21): a 7b or 14b model for most calls, the 72b model only for diagnosis.
Teacher → executor, two tiers
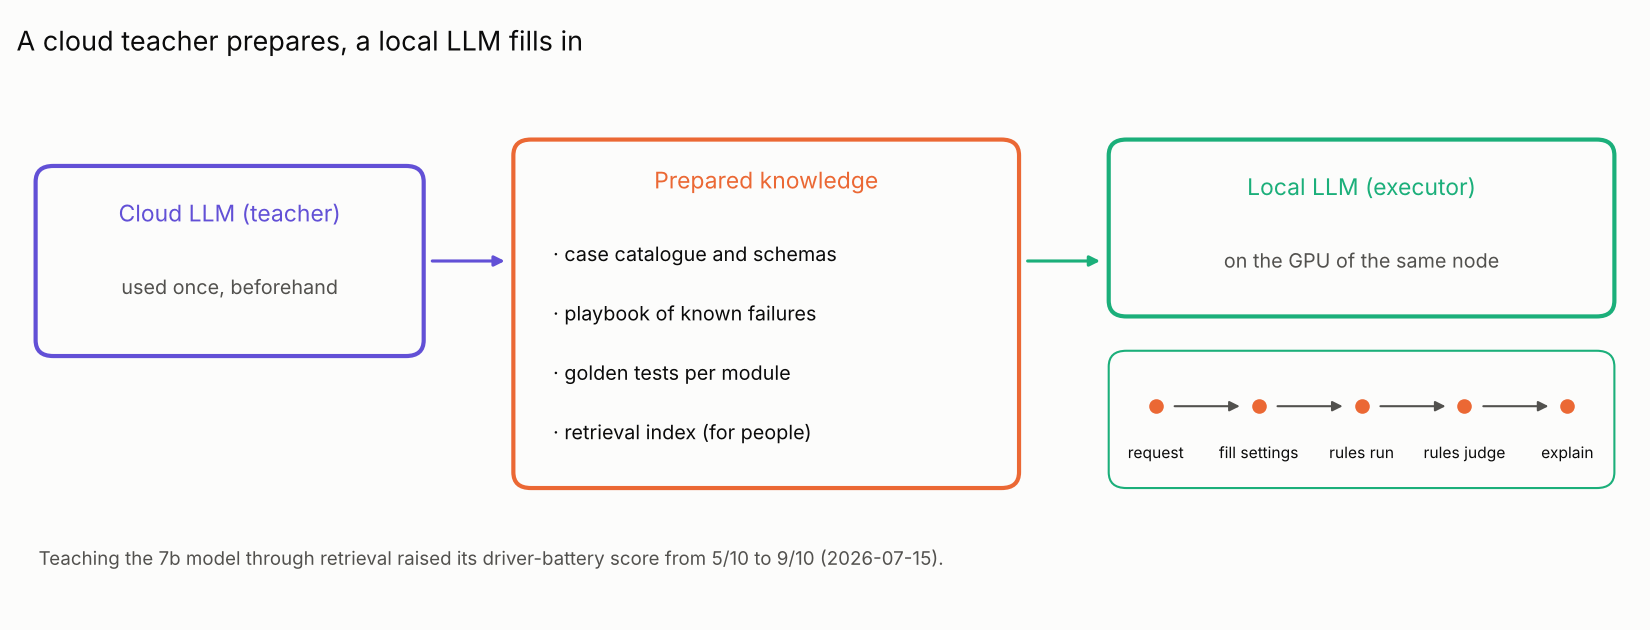
- Teacher (cloud): prepares, once and beforehand, the case catalogue and schemas, the playbook of known failures and the golden tests of each module, plus a retrieval index for people.
- Executor (local): fills the bounded answers of each request. The rules of the agent choose the tier, submit the runs and decide the verdict.
Prepared knowledge carries a small model a long way: teaching the 7b model through retrieval raised its score on the driver battery from 5/10 to 9/10, and on the knowledge battery from 1/8 to 8/8 (2026-07-15).
Status
- The duct-system ladder (1D → OpenFOAM → LBM) ran end to end, automated, on 2026-07-16. The record does not say whether a live LLM or the stand-in (mock) drove that run.
- The station's default model is still
qwen3:14b; the measurements above used qwen2.5. - The numbers are as of 2026-07-15. Models advance quickly, so they need to be re-measured from time to time.